B200 SXM
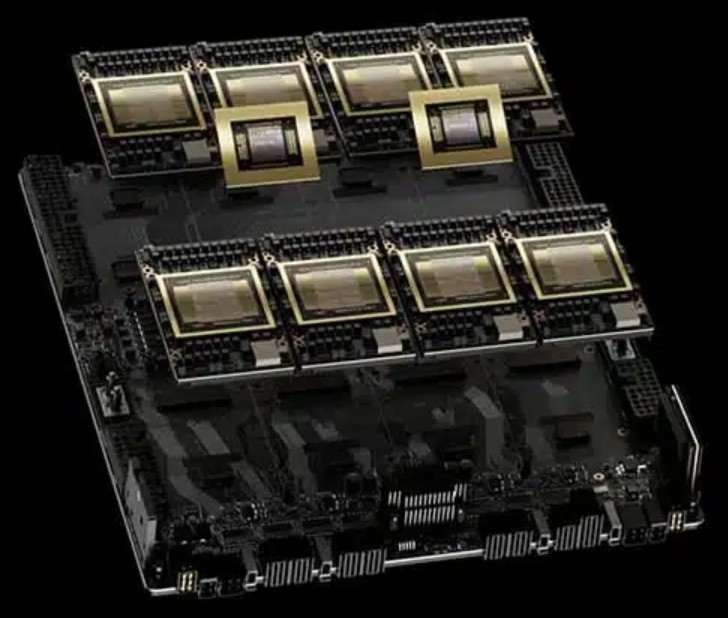
HGX B200, 8-GPU Blackwell
| Indicative price | on quotation, depending on the configuration (price guide) |
|---|---|
| Memory | 180 GB HBM3e per GPU (1,440 GB total; NVIDIA rounds to 1.4 TB) |
| Bandwidth | 7.7 TB/s per GPU |
| Compute | 9 PFLOPS dense FP4 per GPU (72 total, 144 with sparsity) |
| NVLink | 1.8 TB/s NVLink 5 (14.4 TB/s total) |
| Power | 1,000 W per GPU (TGP) |
| Transistors | 208 billion per GPU |
What the machine runs
Frontier-level inference and training, high FP4 throughput. Recommended runtime: vLLM in NVFP4 format.
Positioning
According to NVIDIA, the move to Blackwell reaches up to fifteen times the Hopper generation in inference on the largest models.
Manufacturers
HGX B200 systems from Dell, HPE, Lenovo, Supermicro, ASUS and Gigabyte.
GPUDirect Storage
On platforms fitted with ConnectX cards, GPUDirect Storage technology establishes a direct path between NVMe or NVMe over Fabric storage and GPU memory, bypassing the CPU buffer. Compatible arrays, such as NetApp, VAST, DDN or WEKA, feed training and massive-scale RAG at full speed.
Support
Open stack, maintained by its communities. NVIDIA AI Enterprise option (NIM, NeMo, Triton) with a service-level agreement, licensed per GPU.
Which models fit on B200 SXM?
The machine offers 1,440 GB of memory. 6 of the 7 open models in the catalogue load on it, in the format shown.
| Model | Billion parameters | Most precise format that fits | Sizing page |
|---|---|---|---|
| GLM 5.3 | 744 | FP8 | GLM 5.3 on B200 SXM |
| Kimi K2.7 Code | 1,000 | FP8 | Kimi K2.7 Code on B200 SXM |
| DeepSeek V4 | 1,600 | NVFP4 | DeepSeek V4 on B200 SXM |
| Nemotron 3 Ultra | 550 | FP16 | Nemotron 3 Ultra on B200 SXM |
| MiniMax M3 | 428 | FP16 | MiniMax M3 on B200 SXM |
| Qwen 3.8 27B | 27 | FP16 | Qwen 3.8 27B on B200 SXM |
See the full sizing matrix.
Frequently asked questions
How much does a configured b200 sxm cost for an LLM?
Pricing depends on configuration and supplier. No public price is listed for this configuration; a scoping call helps compare supplier quotes.
Which LLM fits in a b200 sxm?
Depends on the quantization format and the input context. The table on the page indicates the recommended maximum model size.
Which runtimes support the b200 sxm?
vLLM, llama.cpp, Triton Inference Server, depending on the chosen framework. The model, format and GPU combinations measured by QDNA are published in the measurements section.