GB300 NVL72
Rack scale, 72 liquid-cooled GPUs
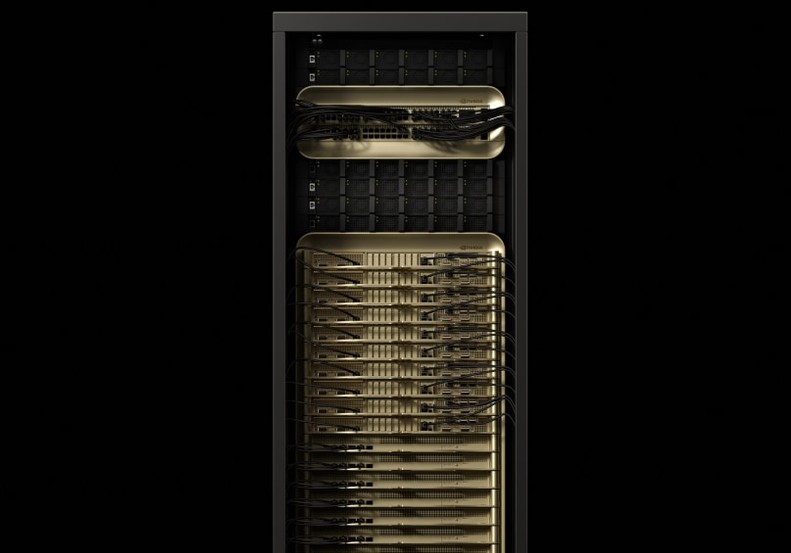
| Indicative price | on quotation: neither NVIDIA nor its integrators publish a price for the rack; analyst estimates reported in the press range from $3.7M to $6.5M and are not prices (price guide) |
|---|---|
| GPU | 72 Blackwell Ultra and 36 Grace (2,592 Arm Neoverse V2 cores) |
| Memory | 20.7 TB of HBM3e according to Lenovo and Supermicro (72 × 288 GB, i.e. 20,736 GB, which the sizing pages round to 20,700 GB); NVIDIA states 20 TB, Dell “up to 21 TB”; 37 TB of fast memory |
| Compute | 1.08 ExaFLOPS dense FP4 (1.44 with sparsity) |
| NVLink | 130 TB/s across a 72-GPU domain |
| Power draw | 132 to 142 kW per rack (NVIDIA reference: 142 kW; HPE and Supermicro: 132 to 140 kW); liquid cooling, about 90% of the heat goes into the liquid |
| Form factor | full MGX rack (48U cabinet at Lenovo) |
What the machine runs
A single 72-chip supercomputer serves frontier models and a private AI cloud. Recommended runtime: disaggregated vLLM with LiteLLM.
Positioning
Large enterprises host their own frontier model in a single rack, in a sovereign AI cloud.
Manufacturers
Rack integration from Dell (PowerEdge XE9712 in IRSS racks), HPE, Lenovo and Supermicro, with liquid cooling. NVIDIA also names contract manufacturers (Quanta, Foxconn, Wistron, Wiwynn, Inventec, Pegatron), whose ranges are not checked here.
GPUDirect Storage
On platforms equipped with ConnectX cards, GPUDirect Storage technology establishes a direct path between NVMe or NVMe over Fabric storage and GPU memory, bypassing the CPU buffer. Compatible storage arrays, such as NetApp, VAST, DDN or WEKA, feed training and large-scale RAG at full speed.
Support
Open stack, maintained by its communities. NVIDIA AI Enterprise option (NIM, NeMo, Triton) with a service-level agreement, licensed per GPU.
Which models fit on GB300 NVL72?
The machine offers 20,700 GB of memory. 7 of the 7 open models in the catalogue load on it, in the format shown.
| Model | Billion parameters | Most precise format that fits | Sizing page |
|---|---|---|---|
| GLM 5.3 | 744 | FP16 | GLM 5.3 on GB300 NVL72 |
| Kimi K3 | 2,800 | FP16 | Kimi K3 on GB300 NVL72 |
| Kimi K2.7 Code | 1,000 | FP16 | Kimi K2.7 Code on GB300 NVL72 |
| DeepSeek V4 | 1,600 | FP16 | DeepSeek V4 on GB300 NVL72 |
| Nemotron 3 Ultra | 550 | FP16 | Nemotron 3 Ultra on GB300 NVL72 |
| MiniMax M3 | 428 | FP16 | MiniMax M3 on GB300 NVL72 |
| Qwen 3.8 27B | 27 | FP16 | Qwen 3.8 27B on GB300 NVL72 |
See the full sizing matrix.
Frequently asked questions
How much does a configured gb300 nvl72 cost for an LLM?
Pricing depends on configuration and supplier. No public price is listed for this configuration; a scoping call helps compare supplier quotes.
Which LLM fits in a gb300 nvl72?
Depends on the quantization format and the input context. The table on the page indicates the recommended maximum model size.
Which runtimes support the gb300 nvl72?
vLLM, llama.cpp, Triton Inference Server, depending on the chosen framework. The model, format and GPU combinations measured by QDNA are published in the measurements section.